When Google open-sourced Kubernetes in 2014 and donated it to the Cloud Native Computing Foundation (CNCF) in 2016, the platform’s primary purpose was straightforward: automate the deployment, scaling, and scheduling of containers across clusters. Today, enterprises apply Kubernetes to a much wider range of infrastructure problems. This article maps out both the established and emerging use cases driving that expansion.
1. Orchestrate Containerized Environments
Container orchestration remains Kubernetes’ core value proposition. It gives IT teams a declarative way to define desired cluster state — how many replicas of a service should run, what resources each Pod can consume, how traffic should be routed — and then continuously reconciles actual state with that definition.
Key orchestration capabilities include:
- Automated rollouts and rollbacks: Deploy new container images gradually and roll back automatically if health checks fail.
- Self-healing: Restart failed containers, reschedule Pods from failed nodes, and replace containers that fail user-defined health checks.
- Horizontal scaling: Scale workloads up or down with a single command or automatically based on CPU and memory metrics via the Horizontal Pod Autoscaler.
- Bin packing: Schedule containers onto nodes based on resource requests, improving hardware utilisation.
Despite Kubernetes’ dominance as the enterprise container orchestration standard, production deployments continue to surface challenges — particularly around security policy enforcement, role-based access control (RBAC) configuration, and observability at scale. These operational concerns remain active areas of tooling investment across the ecosystem.
2. Support Data-Intensive and Stateful Applications
Containers were historically associated with stateless, ephemeral workloads. Running databases, message queues, or large-scale analytics frameworks in containers introduced concerns about data durability, storage performance, and scheduling compatibility. Several developments have narrowed that gap.
Persistent Volumes and StatefulSets — introduced in core Kubernetes — give stateful workloads stable network identities and persistent storage that survives Pod restarts. These primitives underpin the Operator pattern, which encodes domain-specific operational knowledge (such as how to bootstrap and scale a database cluster) into a custom Kubernetes controller.
Spark on Kubernetes is a concrete example of data-intensive workloads moving to the platform. Google Cloud’s Cloud Dataproc service added support for running Apache Spark — a parallel processing framework widely used for large-scale data analytics — on Google Kubernetes Engine (GKE). Running Spark natively on Kubernetes allows teams to share cluster resources with other workloads and simplifies infrastructure management compared to maintaining separate Hadoop clusters. Some scheduling compatibility differences between Spark’s own scheduler and Kubernetes’ scheduler required engineering work to resolve.
Vendors such as Robin Systems have also built hyper-converged Kubernetes platforms targeting big data and machine learning workloads, offering storage, networking, and compute optimisations for those patterns in a single platform.
3. Streamline Multi-Cloud Management
Because Kubernetes presents a consistent API regardless of the underlying infrastructure, it has become a natural abstraction layer for multi-cloud and hybrid-cloud strategies. An enterprise can run Kubernetes clusters on AWS, Google Cloud, and Azure — or on on-premises hardware — and manage workloads through the same tooling and manifests.
Practical multi-cloud patterns enabled by Kubernetes include:
- Workload portability: Define workloads once as Kubernetes manifests and deploy them to any conformant cluster without rewriting infrastructure code.
- Resilience through distribution: Spread replicas across clouds or regions so that a single provider outage does not take down a service.
- Cost optimisation: Route workloads to the cloud provider offering the most favourable pricing for a given workload type at a given time.
- Vendor lock-in mitigation: Avoid coupling application code directly to provider-specific managed services.
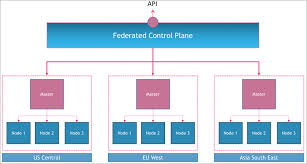
In a typical multi-cloud Kubernetes setup, cluster nodes may span two public cloud providers, or mix private data-centre nodes with public cloud nodes, while a single control plane — or a federation layer — handles scheduling and configuration.
4. Enable Service Discovery
In containerised microservices architectures, individual service instances start and stop continuously. Hard-coding IP addresses is not viable. Kubernetes provides built-in service discovery mechanisms that solve this automatically.
There are two primary approaches:
- DNS-based discovery: CoreDNS (the default DNS server in Kubernetes) creates DNS records for every Service object. Any Pod can reach a service at a stable hostname such as
my-service.my-namespace.svc.cluster.local, regardless of which node the backing Pods are running on. - Environment variable injection: When a Pod starts, Kubernetes injects environment variables for every Service that was active at that time (e.g.,
MY_SERVICE_SERVICE_HOSTandMY_SERVICE_SERVICE_PORT). This approach is simpler but order-dependent and does not reflect services created after Pod startup.
Beyond those two mechanisms, Kubernetes’ kube-proxy component maintains network rules that load-balance traffic across healthy Pod endpoints for each Service, and ReplicaSets ensure the correct number of backing Pods are always available.
5. Perform Container Cluster Federation
Cluster federation refers to the ability to manage multiple distinct Kubernetes clusters as a single logical unit — propagating policies, workloads, and configuration across them. This is distinct from running a single large cluster: federated clusters are individually autonomous but can be coordinated for global deployments or compliance requirements.
Apache Mesos with Marathon was an earlier preferred option for large-scale container federation. The Kubernetes ecosystem has progressively built out federation capabilities, though the approach has evolved significantly over time. The original Kubernetes Federation v1 API was deprecated; the community-driven KubeFed (Federation v2) project took over, focusing on a more flexible, CRD-based model for propagating resources across clusters.
Federation is most useful in environments where:
- Clusters are geographically distributed and normally operate independently.
- Global load balancing or failover across clusters is required.
- Regulatory requirements mandate data residency in specific regions managed as separate clusters.
6. Embrace Next-Generation PaaS with Knative
Knative is an open source platform built on top of Kubernetes that adds primitives for deploying and managing serverless and event-driven workloads. Where raw Kubernetes requires teams to reason about Deployments, Services, and ingress routing, Knative abstracts those concerns behind higher-level objects focused on code and traffic.
Core Knative components include:
- Knative Serving: Manages stateless, request-driven services. Automatically scales Pods to zero when there is no traffic and scales back up on demand — a defining characteristic of serverless platforms.
- Knative Eventing: Provides infrastructure for consuming and routing events from sources such as message queues or webhooks to processing functions.
The practical benefits for event-driven workloads include granular resource billing (pay only for active execution time), reduced operational overhead (no idle capacity to manage), automated scalability, and improved reliability through the underlying Kubernetes self-healing model. Industry analysts have positioned Knative as a potential foundation for the next generation of PaaS offerings — platforms where developers deploy code rather than configuring infrastructure.
7. Manage Virtual Machines Alongside Containers
One of the more significant emerging use cases involves extending Kubernetes control over virtual machines — not just containers. VMware demonstrated Project Pacific at VMworld 2019, an initiative to embed Kubernetes directly into vSphere. The goal was to allow IT administrators to use familiar vSphere tooling to deploy and manage both VMs and containers through a single control plane backed by Kubernetes primitives.
This pattern — sometimes called VM orchestration via Kubernetes — has also appeared in projects such as KubeVirt, a CNCF project that adds a VirtualMachine custom resource to Kubernetes, enabling VM lifecycle management (create, start, stop, live-migrate) through the standard Kubernetes API. This allows organisations running mixed VM and container workloads to converge on a single operational model.
Key Takeaways
Kubernetes started as a container orchestrator and has evolved into a general-purpose platform for managing distributed systems. The table below summarises the use cases discussed:
| Use Case | Core Kubernetes Feature | Maturity (as of 2019) |
|---|---|---|
| Container orchestration | Deployments, ReplicaSets, Scheduler | Production-ready |
| Stateful / data-intensive apps | StatefulSets, Persistent Volumes, Operators | Maturing |
| Multi-cloud management | Portable manifests, conformant API | Established |
| Service discovery | CoreDNS, kube-proxy, Services | Production-ready |
| Cluster federation | KubeFed / Federation v2 | Evolving |
| Serverless / next-gen PaaS | Knative Serving & Eventing | Early adoption |
| VM orchestration | KubeVirt, Project Pacific | Emerging |
The flexibility of the Kubernetes API — particularly its extensibility via Custom Resource Definitions (CRDs) and the Operator pattern — means that this list will continue to grow. Teams evaluating Kubernetes should assess not only its core orchestration capabilities but also the broader ecosystem of extensions that can address workloads well beyond standard containerised microservices.
Original source references: SearchITOperations / TechTarget (searchitoperations.techtarget.com), October 2019.