This article is based on an original post attributed to 126kr.com, discussing how organisations can tune the frequency and depth of their CI/CD pipelines to suit their own risk profiles.
The Most Common Misconception About DevOps
When organisations first explore moving to a DevOps model, a near-universal fear surfaces: “If a developer checks in a single line of code, is it going straight to production?” That fear is understandable, but it rests on a false premise. DevOps does not mandate that every commit triggers a live deployment.
The terms continuous integration (CI) and continuous deployment (CD) are often treated as binary switches — either you have them or you don’t — but in practice they are dials. Your team decides how far to turn each one based on risk appetite, tooling maturity, and the pace of change in your applications.
Defining “Continuous”: It Is Not the Same for Every Team
“Continuous deployment” means moving completed developer changes into a production environment where end users can work with them. The word deploy has a fixed meaning; the word continuous does not. Your organisation owns the definition of continuous that fits your context.
Automated deployment pipelines consume real resources — build agents, test infrastructure, environment capacity, and engineering attention. As a purely practical matter, teams have to decide how often it makes sense to marshal those resources. Common deployment cadences include:
- On every commit — maximum feedback speed, lowest increment size per release
- Nightly — balances feedback with infrastructure cost
- Weekly — common in organisations still building automation confidence
- Monthly — acceptable for applications with a very low rate of change
The Increment of Functionality Problem
The longer the interval between deployments, the more changes accumulate in any single release. This accumulated set of changes — sometimes called the increment of functionality — is directly correlated with deployment risk. A release containing three small changes is far easier to validate, roll back, and diagnose than one containing three months of accumulated work. This is one of the strongest structural arguments for shorter deployment cycles, even when that feels counterintuitive.
“Potentially Deployable” Does Not Mean “Must Deploy”
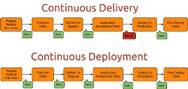
A nuance often lost in CI/CD discussions: the goal of a continuous deployment pipeline is to produce a potentially deployable artifact — not necessarily to deploy it immediately. Your pipeline can build, test, and validate a package against a production-like environment on every cycle without ever pushing it live until a human or a release gate approves it.
This approach — sometimes distinguished as continuous delivery versus continuous deployment — gives organisations the safety net of frequent validation without the perceived disruption of frequent live releases. The pipeline proves the code could go to production; a separate decision determines when it does.
The Hidden Cost of Infrequent Deployments
Choosing a longer deployment interval to reduce disruption trades one risk for another. The most significant hidden costs are:
- Delayed user feedback. Real production feedback only arrives after an actual deployment. The longer the gap, the longer your team is building without knowing whether the previous release met user needs.
- Expensive rework. When a developer receives feedback on a feature shipped weeks or months ago, context has been lost. Fixing it takes longer and risks destabilising newer work built on top of the original change.
- Compounding integration risk. As features pile up between releases, isolating the cause of a production issue becomes progressively harder.
A common pattern in organisations adopting DevOps is to start with monthly or weekly deployments to build confidence in their automation, and then gradually shift toward shorter cycles as the team realises the risks of large increments outweigh the perceived safety of infrequent releases.
How Integrated Should Your Integration Be?
Continuous integration means merging developers’ changes into a shared mainline frequently, rather than leaving branches in isolation for days or weeks. The fundamental goal is that all developers are working from the same codebase at all times, preventing the “integration hell” that occurs when long-lived branches must eventually converge.
Historically, the minimum bar for CI was simply that the application could still compile after a merge (the “don’t break the build” rule popularised by the Windows NT team, among others). Modern CI pipelines go much further, typically including:
- Automated unit tests run by the developer before or immediately after commit
- Static code analysis and linting
- Integration tests that exercise the merged application as a whole
- Contract tests between services in a microservices architecture
- Performance and stress tests (often deferred to a separate stage due to resource cost)
Developers can — and should — write automated unit tests that verify their own code in isolation. But bugs that only surface when components interact can only be caught during integration testing, after code is merged. This distinction matters when deciding where to place which tests in your pipeline.
Calibrating Your Integration Testing Strategy
The ideal is to run all integration tests against a full duplicate of the production environment on every commit. In practice, cost and environment complexity force most teams to make trade-offs. Two variables determine where tests end up in your pipeline:
- How easy it is to keep the integration environment in sync with production. Environment drift is a hidden tax on test reliability. If your integration environment frequently diverges from production, test results become less meaningful.
- How resource-intensive the tests are. Functional correctness tests are usually fast and cheap. Stress tests, user-acceptance tests, and full end-to-end tests can be slow and expensive to run on every commit.
A practical approach many teams use is a tiered test strategy:
- On every commit: unit tests and fast integration smoke tests
- On every build (nightly or per-branch merge): full functional integration tests
- On release candidates: performance, stress, and user-acceptance tests
The important principle is that deferring a test increases the cost of fixing any defect it catches, because the developer must re-establish context from work done further in the past. As your pipeline becomes more efficient, the economics shift: it becomes cheaper to run more tests earlier, and teams naturally pull tests further left in the process.
The Natural Evolution of a CI/CD Programme
Organisations rarely reach an optimal CI/CD cadence on day one. A realistic progression typically looks like this:
- Establish the pipeline. Get automated builds and basic tests running. Deploy infrequently (weekly or monthly) to build confidence in automation.
- Increase deployment frequency. As confidence grows, the team notices that large increments of functionality are themselves a source of risk, and begins deploying more often.
- Move tests left. As the pipeline matures, expensive tests that were deferred to the deployment stage are moved into the integration stage, or even into per-commit validation.
- Reach a sustainable balance. The team finds a cadence that minimises overall risk — covering both deployment disruption and the risk of delayed feedback — and continues to adjust as the application and organisation evolve.
Key Takeaways
- CI and CD are spectrums, not binary states. Your team decides where on each spectrum to operate.
- Longer deployment intervals reduce disruption frequency but increase per-release risk and delay user feedback.
- “Potentially deployable” is a valid outcome of a CD pipeline — actual deployment can be gated by humans or automated release policies.
- The right integration testing strategy is determined by environment parity costs and test resource costs, not by ideology.
- As pipeline maturity increases, the economics of shifting tests earlier improve. Treat your CI/CD posture as something that evolves continuously alongside your team’s capabilities.
DevOps does not impose a one-size-fits-all deployment rhythm on your organisation. It gives you the tooling and practices to make deployment safe enough to do more frequently — and then leaves the decision about how frequently firmly in your hands.