Original article source: hackernoon.com
The “Everything-as-Code” Problem
DevOps, at its core, is about replacing manual, undocumented, person-dependent processes with automation. The out-of-date Wiki page that nobody maintains, the one engineer who knows how to configure the servers, the DBA you have to call every time a migration goes wrong — DevOps replaces all of that with repeatable, version-controlled code.
The result is a world of everything-as-code: infrastructure-as-code, networking-as-code, database migrations as code. Tools like Terraform, Ansible, Chef, Puppet, and SaltStack have made this possible at scale. But this shift raises an uncomfortable question for testing teams: whose responsibility is it to test all of this new code?
Most testing teams are still scoped to the core application. They validate that features work to specification and that regressions haven’t crept in. But the automation pipeline that builds, configures, deploys, and monitors that application? That is largely untested — or tested informally, at best.
Which Code Are We Actually Testing?
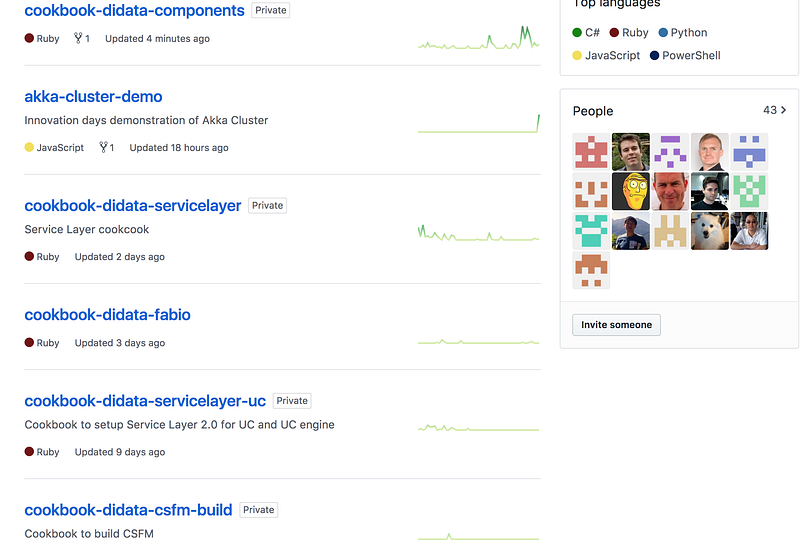
DevOps has materially increased the volume, complexity, and variety of code that a team produces. Consider a team building C# microservices and using Chef for configuration management of their environments. Chef cookbooks that go beyond simple out-of-the-box functionality require Ruby extensions. The result: Ruby can easily become the second-largest language in a GitHub organisation, even on a predominantly .NET team.
The same pattern applies to Puppet, Ansible, and SaltStack — extend them to fit your environment and you are writing Python or Ruby. These custom libraries are commonly pushed into production with no test coverage whatsoever. They are not considered “the application”, so they do not make it into the test plan.
Stage by Stage: The Pipeline Testing Gap
A typical DevOps pipeline — whether modelled on IBM’s reference architecture or any other — involves multiple environments: development, staging, and production. The argument for having a separate staging environment is to catch issues before they reach users. But if every environment is software-defined, built from the same tested Infrastructure-as-Code, the value proposition for long-running staging environments weakens.
Cloud infrastructure can be provisioned in seconds. Ephemeral, per-build environments give you a clean, known configuration every time — eliminating the “it works on my environment” problem. CI/CD pipelines make this achievable for build and unit-test stages. The problem is what happens next: the artefact gets handed to a testing team that may operate on a completely different cadence, working against a long-lived environment that has accumulated undocumented changes.
One of the most common and dangerous anti-patterns in DevOps is an engineer SSHing into a server, making a quick firewall change or configuration tweak to fix a problem, and not feeding that change back into the Chef recipe or Ansible playbook. The next deployment overwrites it — or worse, the change persists and creates a snowflake environment that nobody fully understands. This is precisely the kind of drift that a mature testing capability should be catching, but testers are rarely involved at this layer.
The Untested Code That Surrounds Your Application
Beyond the application itself, a modern DevOps team produces a significant body of supporting code that almost never appears in a test plan. This includes artefacts across the full delivery lifecycle:
Development and Source Control
- Pre-merge commit hooks
- Build scripts
- Packaging scripts
Deployment
- CI/CD pipeline scripts and configurations
- Custom modules and extensions for Chef, Ansible, Puppet, etc.
Monitoring and Alerting
- Responsive monitoring scripts (auto-remediation, auto-scaling triggers)
- Alerting integrations and notification pipelines
For anything beyond a trivial application, these are not five-line scripts. They can be large, complex, poorly structured, and carrying significant business risk. A failure in a deployment script can take down production just as surely as a bug in the application itself. Yet they sit outside the scope of most testing teams by default.
If you were to draw a quality pyramid and explicitly mark all of this infrastructure code as “out of scope for testers”, it forces a direct question: what is the actual mandate of the testing function? Is it purely to validate that delivered features meet specification? Or is it to protect the organisation from quality failures wherever they arise?
What Testers Should Be Doing in a DevOps Environment
A testing professional in a mature DevOps organisation has an opportunity to add value well beyond their traditional scope. Here are concrete activities that extend the tester’s remit appropriately:
- Audit and challenge automation repeatability. Understand the deployment and provisioning pipeline end-to-end. Identify steps that are manual, undocumented, or change frequently — these are your highest risk points.
- Treat test environments as immutable and build-bound. Advocate for ephemeral environments that are created fresh for each test run and destroyed afterwards, ensuring tests always run against a known, clean configuration.
- Extend test coverage to the pipeline itself. Apply the same rigour to deployment scripts, packaging scripts, and configuration management code that you apply to application code. Unit tests for Ansible roles and Chef cookbooks are entirely achievable.
- Act as a quality advocate for DevOps engineers and SREs. Many operations-focused engineers have limited exposure to test theory, test design, and test-driven approaches. Testers can provide coaching and establish shared quality standards across the team.
- Champion code quality discussions for tooling, not just applications. Raise code review standards, coverage expectations, and refactoring conversations for the full codebase — including the infrastructure and automation layer.
The Bottom Line
DevOps has not made testers redundant — it has made the testing challenge significantly larger. The surface area of code that carries production risk has expanded dramatically. Testing teams that continue to treat infrastructure code, deployment scripts, and monitoring integrations as someone else’s problem are leaving a large portion of the system unvalidated.
The most effective testers in a DevOps world are those who follow the code wherever it goes: into Terraform modules, into CI/CD pipelines, into Chef cookbooks, and into the monitoring layer. Deploying with confidence every single time requires quality to be a shared concern across the entire delivery system — not just the application at its centre.