This article is based on reporting originally published by SiliconAngle in July 2018. Quotes, figures and attributions are drawn from that source.
Why Serverless Is More Than Just Hype
Customer engagement platform Braze sends more than 1.5 billion messages a day and interacts with more than 1 billion consumers a month. That scale brings an acute infrastructure challenge: demand for computing resources fluctuates dramatically depending on the volume of data Braze must transform to support personalised messaging campaigns.
“At one point we may have 100 servers running, and at another we may have 1,000,” said Sal Poliandro III, director of DevOps and security at Braze. The company used to scale its cloud infrastructure based on a set of metrics that amounted to an educated best guess. Then it migrated core scaling logic to AWS Lambda, Amazon’s serverless computing platform.
The result: scaling is now fully automated. An algorithm determines required capacity and immediately triggers infrastructure scaling through Lambda functions. “We used to scale based on peak loads,” Poliandro said. “With serverless, we don’t have to worry about that.” He estimates that for a typical development team, the process is at least ten times faster than provisioning servers manually.
Braze is one of many organisations discovering that serverless computing — and its subcategory, Function-as-a-Service (FaaS) — can eliminate infrastructure drudgery while delivering meaningful cost savings and near-infinite elasticity.
What Serverless Actually Means
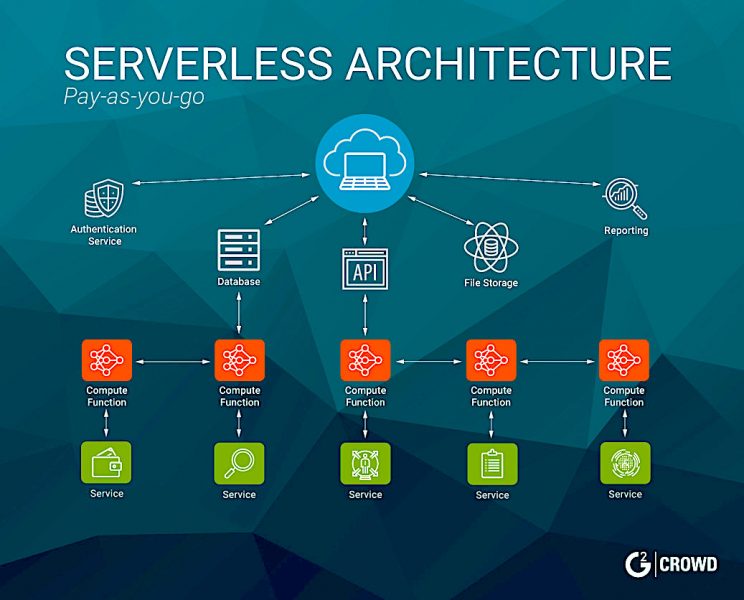
Despite the name, serverless computing still runs on servers. The distinction is that developers do not provision, configure, patch or manage those servers. Instead, discrete units of code — called functions — execute automatically in response to an event, whether triggered by a user action, a scheduled timer, an API call or a message queue.
Key characteristics of the serverless model:
- Event-driven execution: Functions run only when triggered. No event, no cost.
- Stateless by design: Each function invocation starts with a clean context. No session history is carried between invocations unless explicitly passed in or retrieved from external storage.
- Pay-per-invocation billing: Customers pay only for the compute time consumed during execution, not for idle server capacity.
- Automatic horizontal scaling: The provider scales function instances up or down — including to zero — without operator intervention.
- Millisecond cold-start latency (at scale): Spinning up a function takes milliseconds rather than the hours or days that manual virtual machine provisioning can require.
In contrast, conventional application deployment requires pre-allocating CPU, memory and storage, plus a suite of platform software. Those resources remain provisioned — and billed — even during idle periods. Overprovisioning drives up costs, wastes capacity and contributes to server sprawl: cloud instances that are forgotten but still incurring charges.
Real-World Use Cases
Serverless is a natural fit for workloads that are:
- Spiky or unpredictable: News sites that see traffic surge during breaking events, or sports platforms that spike when a team enters the playoffs, benefit from paying only for the traffic they actually receive.
- Event-driven data pipelines: A user uploading an Excel file can trigger a Lambda function to convert it to JSON and write it to a data lake — without any standing server.
- Mobile back-ends: A smartphone app requesting a weather forecast or directions passes a location parameter and receives a single targeted result. The function executes and terminates immediately.
- Image and media processing: When a user updates a profile photo, a serverless function can automatically resize it and replicate it to CDN origins.
- High-performance computing: Fannie Mae (Federal National Mortgage Association) migrated Monte Carlo risk-analysis simulations from on-premises servers to AWS Lambda. In one simulation covering approximately 20 million mortgages, the serverless approach completed the job more than four times faster than the previous setup — what AWS described as a “supercomputer in the cloud.”
A Decade in the Making: The Provider Landscape
Serverless concepts are not new. Google’s App Engine introduced elements of metered billing as far back as 2008. The model gained significant momentum when Amazon launched AWS Lambda in 2014. The major cloud providers now all offer FaaS platforms:
- AWS Lambda — Amazon Web Services
- Google Cloud Functions — Google Cloud
- Azure Functions — Microsoft Azure
- IBM Cloud Functions (based on Apache OpenWhisk) — IBM Cloud
Beyond the hyperscalers, a broad ecosystem of open-source frameworks and commercial tools has emerged, including options for on-premises serverless deployment. Enterprises increasingly concerned about vendor lock-in are evaluating these alternatives.
Adoption figures reported around 2017–2018 reflect how quickly the space was growing. An analysis of 1,500 organisations by Cloudability found that use of serverless platforms grew more than sevenfold in Q4 2017, albeit from a small base. RightScale reported that serverless was the fastest-growing extended cloud service in 2017 among nearly 1,000 IT professionals surveyed, with adoption growing from 12 to 21 percent.
Enterprise adoption has also moved faster than many expected. Tim Wagner, general manager of AWS Lambda, noted at the time that large enterprises including Capital One, Hearst Corp. and the Financial Industry Regulatory Authority (FINRA) were among the fastest-growing Lambda users.
The Two Core Characteristics: Stateless and Event-Driven
Understanding serverless’s strengths and limitations requires understanding two defining properties.
Statelessness
A serverless function has no persistent memory of previous invocations. It receives its inputs, executes, returns a result and terminates. “It’s like a blank slate each time, but it’s highly efficient because you’re not managing a lot of thick application logic,” said James Kobielus, an analyst at Wikibon.
This is powerful for discrete queries — a weather lookup, a file format conversion, a database write — but problematic for workflows that require context across multiple steps, such as a multi-step e-commerce checkout or a billing system that must reconcile prior state.
Event-Driven Execution
Functions run in response to defined events: an HTTP request, a file upload, a database record change, a message on a queue, a scheduled cron trigger. This means zero resource consumption when no events are occurring.
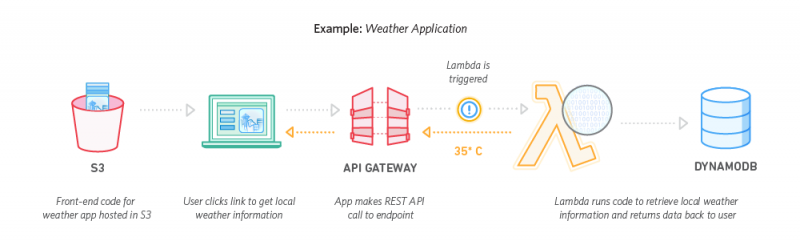
“You can set it up so if one event comes in, then one function runs. If a million come in, you fire off a million,” said Craig Lowery, a research director at Gartner. Horizontal scaling is automatic, elastic and managed entirely by the provider.
Where Serverless Falls Short
Serverless is not a universal compute model. Current limitations include:
- Stateful workflows: Applications that require complex, ordered transactions — shopping carts, billing systems, financial reconciliation — are poor fits for a purely stateless model without additional orchestration layers.
- Long-running processes: Most FaaS platforms impose maximum execution time limits per invocation, making them unsuitable for workloads that run for extended periods without architectural adaptation.
- Debugging and observability complexity: Distributed, ephemeral functions are harder to trace and debug than monolithic or container-based applications. Tooling is maturing but still catching up.
- Vendor lock-in: Functions written for Lambda may not be portable to Azure Functions or Google Cloud Functions without modification. Open-source frameworks such as OpenWhisk and the Serverless Framework attempt to mitigate this.
- Cold-start latency: Functions that have not been invoked recently may incur a startup delay before execution, which can affect latency-sensitive applications.
“Serverless architectures move complexity out of the application and into the connectivity,” said Lee Atchison, senior director of strategic architecture at New Relic. “It’s not a solution to everything. It creates its own problems as well as solves them.”
Rich Sharples, senior director of product management at Red Hat, predicted that few companies would go all-in on serverless: “Your general IT shop will have a mix.”
Bridging the Gap: Containers, Orchestration and Stateful Extensions
Platform vendors are actively working to extend serverless beyond its current boundaries.
Microsoft introduced Virtual Kubelets (announced December 2017) to enable containers to run either functions or full applications while retaining serverless billing granularity and automated infrastructure provisioning. Microsoft also offers Durable Functions, a programming model that adds stateful orchestration on top of Azure Functions by persisting state externally between invocations.
AWS introduced Fargate (announced late November 2017) to allow containers to run without managing servers or clusters, blending the operational simplicity of serverless with the flexibility of containers.
Kobielus of Wikibon has even suggested that blockchain’s immutable ledger could theoretically compensate for statelessness in database-intensive scenarios by providing a complete auditable narrative of function calls across a distributed fabric — though this remains speculative.
What Serverless Means for Developers
Serverless has an advantage that doesn’t show up in ROI spreadsheets: developers genuinely like it. Removing infrastructure provisioning from the development loop lets engineers focus on writing and shipping code.
“It enables our applications and operational engineers to think about their responsibilities in a way that’s more meaningful to them,” said Braze’s Poliandro. “They can deploy faster because they don’t have to worry about the infrastructure around it.”
However, adopting serverless requires a significant mental shift. Developers must:
- Design for statelessness and idempotency from the start.
- Embrace event-driven, asynchronous programming patterns.
- Understand how to chain functions and manage state externally (for example, using DynamoDB, Redis or a durable orchestrator).
- Rethink monitoring and observability strategies for ephemeral, distributed execution.
“To go to Lambda is a substantial code rewrite,” conceded Mark Ryland, director of AWS’ Office of the CISO. Gartner’s Lowery found through a study of five organisations moving up the serverless learning curve that all became advocates once they stopped applying traditional application-development norms. “Once they kicked those old expectations, they were able to realise the benefits,” he said.
A Practical Migration Strategy
Organisations do not need to rewrite existing applications from scratch to benefit from serverless. A phased approach reduces risk:
- Identify discrete, event-driven functions within existing applications — image processing, file conversion, notification dispatch, data validation — that can be extracted and deployed as standalone functions.
- Implement new features as serverless functions rather than adding to existing monoliths or microservices.
- Split user interface components from business logic and data access layers, converting appropriate microservices into functions over time.
- Experiment in low-risk environments before committing to serverless for mission-critical workloads.
- Invest in observability tooling early: distributed tracing, structured logging and alerting are essential in a functions-based architecture.
Rohit Akiwatkar, a technology consultant at Simform, summarised the outcome: “Over time, the number of functions will grow, and the agility and velocity of your development team will increase.”
The Strategic Imperative for Engineering Leaders
AWS CEO Andy Jassy said in 2017 that if Amazon were being built today, it would be built on a serverless platform. Microsoft CEO Satya Nadella stated at Microsoft Build that “serverless computation is going to fundamentally change not only the economics of what is back-end computing, but it’s going to be the core of the future of distributed computing.”
For engineering leaders, the practical advice from analysts is straightforward:
- Serverless is not a passing trend — the major cloud providers have committed enormous engineering resources to it.
- Start building internal expertise now. The learning curve is real, and the talent market increasingly expects serverless skills.
- Adopt incrementally. Identify the highest-ROI, lowest-risk workloads and gain experience before attempting large-scale migrations.
- Do not attempt a direct “lift and shift” of existing applications. Serverless requires architectural rethinking, not just re-hosting.
“You have to have a plan to adopt this technology for the long term or you will not have access to the talent you need,” Gartner’s Lowery warned. “Developers will expect it.”
Between containers, microservices and serverless computing, the past decade has introduced more innovation in how applications are built and deployed than the preceding two decades combined. For teams still absorbing DevOps, cloud-native architecture and container orchestration, serverless may feel like yet another wave to survive. But the economics — pay only for what you use, scale to zero, deploy in milliseconds — make it a compelling model for an expanding share of modern workloads.