This article is based on a case study originally published on devopsonline.co.uk, authored by Senior Engineer Jitander Kapil, describing how Chaos Engineering principles were applied to resolve persistent production and UAT environment issues in a large enterprise transformation programme.
The Challenge: DevOps as a Service for Production Stability
Most DevOps adoption stories centre on greenfield projects — shifting left, embedding CI/CD pipelines, and integrating testing early in the development lifecycle. But what happens when the immediate problem is not slow delivery, but a system that is actively breaking in production?
That was the situation Kapil faced. As DevOps Lead, his first mandate was not to build out a CI/CD practice — it was to stabilise an enterprise system experiencing recurring production blockers and environment failures. The standard DevOps playbook, designed for Agile/Kanban delivery of new features, needed to be adapted for a damage-control scenario on an existing large-scale system.
The Problem: Cascading Downtime Across Environments
The team faced a range of environment instability issues that were blocking delivery at multiple stages:
- Production blockers with downtimes ranging from 5 minutes to 1 hour
- UAT environment outages lasting 30 minutes or more
- QA downtime of up to 4 hours following deployment changes
- Infrastructure and network instability causing unpredictable failures
Adding complexity to the situation: eight separate squads — working across multiple technology stacks — were sharing a single delivery pipeline and deploying continuously. This was not a small new project. It was a large enterprise system transformation, meaning failures had wide blast radius and high business impact.
The Idea: Apply Chaos Engineering to Find and Fix Weaknesses
Chaos Engineering is the discipline of deliberately introducing controlled failures and turbulent conditions into a distributed system in order to surface hidden weaknesses before they become unplanned outages. The core insight is that complex systems will inevitably experience unexpected failures — the question is whether you discover those failure modes proactively, in a controlled experiment, or reactively, during a production incident.
In this context, Chaos Engineering was not just applied to production resiliency testing in the traditional Netflix/Simian Army sense. It was used as a structured methodology to understand and eliminate the environmental instability that was blocking the team’s ability to deliver.
Organisational Structure: Two Groups, One Goal
Effective Chaos Engineering requires clear separation of responsibilities. In this implementation, two groups operated in parallel:
- Chaos Teams (experimental group): Responsible for designing and executing controlled failure experiments — simulating server failures, severed network connections, environment crashes, and deployment-triggered outages.
- DevOps War Room team (control group): Responsible for monitoring system behaviour during experiments, capturing the impact, and coordinating remediation. Operating from a centralised “Phoenix War Room,” this team tracked real-time system state across all environments.
Establishing a steady-state baseline was the first step — defining what “normal” looked like for production, QA, and UAT environments (e.g., 24×7 availability and zero unplanned downtime as the target). Without a clear steady-state definition, it is impossible to know whether an experiment has caused a meaningful deviation.
Four Steps to Running a Chaos Engineering Experiment
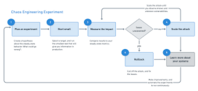
The team followed a structured four-step cycle for each experiment:
- Hypothesise the failure outcome. Before introducing any failure, the team defined what they expected to happen. For example: “If the QA environment loses its database connection during a deployment, the pipeline will fail and block all eight squads for X minutes.”
- Design a targeted experiment. Engineers created controlled scenarios that reflected real failure patterns they had already observed — environment outages, server malfunctions, severed network connections. Experiments were scoped to avoid unnecessary blast radius.
- Run the experiment and compare results. If the experiment revealed a weakness the team had not anticipated, it was logged as a successful chaos experiment. If the system held, the team expanded the hypothesis and tested more extreme conditions.
- Fix weaknesses before they become system-wide failures. Discovered weaknesses were addressed immediately — before being exposed by an unplanned production event. This shifted the team from reactive firefighting to proactive hardening.
The Solution: Temporary Environments and Automatic Failure Recovery
One of the key operational changes driven by this approach was adopting a policy of ephemeral (temporary) environments for all non-production work. Rather than relying on long-lived shared QA and UAT environments — which were fragile, contested across eight squads, and difficult to recover quickly — environments were provisioned on demand and discarded after use.
This approach has several concrete benefits:
- Eliminates environment contention between squads sharing a single pipeline
- Dramatically reduces recovery time — a broken ephemeral environment is replaced, not repaired
- Forces infrastructure-as-code discipline — environments must be fully automated to be ephemeral
- Surfaces hidden dependencies that only appear when an environment is rebuilt from scratch
The broader goal was to build systems that could automatically detect and respond to component failures without human intervention — reducing the mean time to recovery (MTTR) and eliminating the long tail of environment-related blockers that had been degrading team velocity.
Key Takeaways for DevOps Teams
This case study offers several practical lessons for teams dealing with environment instability in complex, multi-squad delivery contexts:
- Chaos Engineering is not only for Netflix-scale systems. The principles apply equally to enterprise transformation programmes suffering from environment fragility.
- Define your steady state first. You cannot measure the impact of a failure experiment without a clear baseline for what healthy looks like.
- Separate experimentation from operations. A dedicated chaos team running experiments, alongside an operations team absorbing and responding to them, creates productive feedback loops without operational chaos.
- Ephemeral environments are a force multiplier. When environments are reproducible on demand, a failed environment stops being a blocker and becomes a non-event.
- Proactive failure discovery beats reactive incident response. Every weakness found in a chaos experiment is a production incident that did not happen.
For teams struggling with the gap between DevOps ideals and the messy reality of a large, unstable production system, Chaos Engineering offers a structured way to take back control — by deliberately introducing the chaos before it introduces itself.