In today’s competitive technology landscape, organisations need two things above all else: stability and adaptability. DevOps — short for Development and Operations — is a software delivery philosophy and cultural movement designed to provide both. It is not a job title, a single tool, or a rigid framework. Instead, it is a set of practices that brings development and operations teams together, shortening feedback loops and enabling continuous delivery of value.
Despite its well-documented benefits, many organisations treat DevOps adoption as a burden rather than an opportunity. Implementation is rarely straightforward, and the challenges are real. Understanding those challenges before you begin is the first step toward overcoming them.
“DevOps is not a goal, but a never-ending process of continual improvement.”
— Jez Humble, co-author of Continuous Delivery
What Is DevOps?
DevOps emerged from the recognition that traditional software delivery models — where developers write code and then “throw it over the wall” to operations to deploy and maintain — produce slow release cycles, poor quality, and organisational friction. By breaking down those silos, DevOps teams can:
- Release software more frequently and with greater confidence
- Detect and resolve defects faster through continuous testing and monitoring
- Share responsibility for both delivery speed and system reliability
- Build a feedback culture that drives continuous improvement
DevOps is closely associated with practices such as continuous integration (CI), continuous delivery (CD), infrastructure as code (IaC), automated testing, and blameless post-mortems. Tools like Git, Jenkins, Docker, Kubernetes, Terraform, and Prometheus are commonly used to operationalise these practices — but the tools are secondary to the cultural and organisational changes required.
Common DevOps Implementation Challenges
Organisations of every size encounter obstacles when adopting DevOps. The following are the most frequently cited challenges, along with practical guidance on how to address each one.
1. The Development vs. Operations Divide
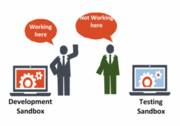
The foundational tension in any DevOps adoption is the historical gap between developers and operations engineers. Developers are incentivised to ship new features quickly and are comfortable with change. Operations teams are incentivised to keep systems stable and are wary of untested deployments. These differing objectives — and the mutual distrust that often accompanies them — are the root cause of many delivery failures.
DevOps does not ask either team to abandon its expertise. Instead, it asks both to share accountability for outcomes. Practically, this means:
- Developers taking responsibility for the operability of their code (logging, alerting, runbooks)
- Operations engineers participating in sprint planning and design reviews
- Joint on-call rotations that give developers visibility into production behaviour
- Shared dashboards and metrics that make system health transparent to everyone
2. Cultural Change
DevOps is, before anything else, a cultural shift. It requires people to collaborate across boundaries they may have spent years maintaining, to accept blame-free retrospectives, and to trust colleagues from different disciplines. This is often harder than adopting any new tool or pipeline.
Cultural change cannot be mandated from above and completed in a quarter. Effective approaches include:
- Starting small: Identify a willing pilot team and build visible success before rolling out more broadly.
- Growing internal champions: Individuals who have experienced DevOps benefits firsthand are far more persuasive than external consultants or management mandates.
- Investing in training: Skills gaps in CI/CD pipelines, cloud infrastructure, or automated testing will undermine even the most enthusiastic teams.
- Celebrating learning from failure: Blameless post-mortems signal that the organisation values improvement over punishment.
3. Toolchain Complexity
The DevOps ecosystem offers a vast and growing selection of open-source and commercial tools. While this is ultimately an advantage, it creates a real challenge during adoption: teams can easily become overwhelmed by tool choices, or accumulate tools that overlap in function and create integration headaches.
More dangerous than choosing the wrong tool is deploying a tool nobody has been trained to use. An untrained team using a CI/CD platform incorrectly can introduce security vulnerabilities, break deployment pipelines, or create infrastructure drift. Key principles for toolchain decisions:
- Prioritise tools your team can actually use and support, not just the most popular options.
- Standardise on a core toolchain before expanding it.
- Treat tool training as a mandatory investment, not an optional extra.
- Evaluate security implications — particularly around secrets management, access controls, and supply chain integrity — before adoption.
4. Legacy Systems and Technical Debt
Many organisations carry significant legacy infrastructure: monolithic applications, on-premises systems built on older architectures, and tightly coupled dependencies that predate modern API design. These systems are often incompatible with the automation-first, containerised, cloud-native approaches that DevOps pipelines assume.
Attempting to bolt modern tooling onto an unchanged legacy estate rarely produces good results. Instead, organisations should:
- Assess which legacy systems can realistically be modernised, strangled (incrementally replaced), or encapsulated behind APIs.
- Prioritise the systems that most constrain delivery speed.
- Accept that some legacy systems will need significant investment before full DevOps practices apply to them.
- Avoid creating two-tier IT estates where new projects run on modern pipelines but critical legacy systems are excluded — this limits the overall impact of DevOps adoption.
5. Process and Workflow Changes
DevOps does not prescribe a single delivery process. There is no universal framework that applies to every organisation, and DevOps does not come with predefined KPIs. This flexibility is a strength, but it can also feel like a vacuum to teams accustomed to rigid waterfall or ITIL-based processes.
The transition from heavyweight change-approval processes to lightweight, automated deployment pipelines requires genuine procedural change. Audit trails, change records, and approval gates still exist in mature DevOps environments — they are simply automated, faster, and evidence-based rather than manual and bureaucratic. Teams navigating this transition should:
- Map existing processes before replacing them — understand why controls exist before removing them.
- Collaborate with security and compliance stakeholders early, not after pipelines are built.
- Allow teams some autonomy in choosing their workflow, within agreed quality and security guardrails.
6. Resistance to Change
Individual resistance is one of the most underestimated obstacles in DevOps adoption. People build skills, habits, and professional identities around specific ways of working. A mandate to change all of that — especially if the rationale is poorly communicated — naturally generates anxiety and pushback.
A common misconception is that DevOps automation will eliminate jobs. In practice, automation shifts the work rather than eliminating it: routine manual tasks are replaced by higher-value activities like pipeline engineering, reliability work, and capacity planning. Addressing resistance effectively requires:
- Transparent communication about what is changing and why.
- Gradual rollout — piloting DevOps on a bounded project reduces risk and gives hesitant team members time to observe results.
- Investing in upskilling so that people feel equipped, not sidelined.
- Acknowledging that some roles will evolve, and providing a credible path for individuals to grow into those new roles.
7. Lack of a Unified Organisational Vision
DevOps adoption fails when different parts of the business pull in different directions. A common failure mode is treating DevOps as a purely technical initiative owned by engineering, while business units, product managers, and security teams continue to operate with conflicting priorities and separate metrics.
Successful DevOps transformations are driven by a shared vision that spans engineering, operations, security, and the business. This means:
- Leadership alignment on what DevOps success looks like — and agreement on metrics such as deployment frequency, lead time for changes, mean time to restore (MTTR), and change failure rate.
- Issues being resolved collectively, not in silos — a production incident is not just an operations problem.
- Cross-functional teams that include security (DevSecOps) and product stakeholders, not just developers and engineers.
Measuring DevOps Success
One practical way to align teams around a shared vision is to adopt well-established DevOps metrics. The DORA (DevOps Research and Assessment) research programme has identified four key metrics — deployment frequency, lead time for changes, change failure rate, and time to restore service — as reliable indicators of software delivery performance. Using shared metrics removes ambiguity about what improvement looks like and creates a basis for honest, data-driven conversations.
Conclusion
DevOps is not a product you can buy or a project you can complete. It is an ongoing discipline that requires sustained investment in culture, tooling, processes, and people. The challenges outlined above are real, but none of them are insurmountable. Organisations that have successfully adopted DevOps consistently report shorter release cycles, higher deployment reliability, faster incident recovery, and greater team satisfaction.
The path forward is pragmatic: start with a willing team, demonstrate measurable results, invest in training and tooling, and build from there. DevOps is, as Jez Humble observed, a never-ending process of continual improvement — and that is precisely what makes it worth the effort.