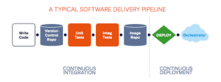
Continuous Integration and Continuous Deployment (CI/CD) is the practice of automating the software build, test, and release process so that code changes move from development to production reliably and rapidly. As organizations adopt microservices architectures—where dozens or hundreds of independently deployable services interact—the pressure to implement robust CI/CD pipelines has intensified. But CI/CD benefits virtually any software project, not just those running on modern container platforms.
Despite the clear advantages, implementing CI/CD is genuinely difficult. Teams must design pipeline workflows, choose between end-to-end integrated platforms and self-assembled toolchains, and ensure that automation touching production systems is safe and correct. The wrong approach can slow down releases instead of accelerating them, erode team confidence, and create outages that affect real users.
The consistent theme across successful CI/CD rollouts is straightforward: go slow, then grow. The following four strategies—originally outlined by Tom Petrocelli, contributing analyst at Amalgam Insights, and published on CMSWire—give DevOps teams of any size a framework for reducing risk during adoption.
1. Be Selective About the Code You Automate First
One of the most common mistakes teams make is deciding to automate everything at once. Rushing to run all code types through a new pipeline dramatically increases risk, because pipelines often need iteration and tuning before they are reliable for a given artifact type.
A more effective approach is to start with a single class of code. Good candidates for an initial pipeline include:
- Infrastructure as Code (IaC) files such as Terraform configurations or Ansible playbooks
- YAML or JSON configuration files used to define environments or container workloads
- Database migration scripts (SQL files managed through a tool like Flyway or Liquibase)
By scoping automation to one artifact type, any pipeline defects affect only a narrow slice of the overall system. The team gains real experience tuning the pipeline—handling secrets, environment variables, approvals, and rollbacks—before widening the blast radius to more critical code paths.
2. Take an Incremental Approach to Pipeline Stages
A complete CI/CD pipeline has many stages: source control triggers, build, unit testing, integration testing, security scanning, artifact publishing, environment promotion, smoke testing, and production deployment. Automating all of these at once compounds complexity and makes it harder to isolate failures.
Instead, automate one stage at a time. A sensible sequence might look like this:
- Automate the build step—compile code and produce an artifact on every commit.
- Add automated unit tests that run on every build.
- Introduce automated merges to a shared integration branch once tests pass.
- Extend the pipeline to deploy to a staging environment automatically.
- Finally, add controlled production deployment with approval gates or feature flags.
This incremental approach lets the team verify that each stage is reliable and error-free before adding the next layer of automation. It also makes it far easier to debug problems, because each stage was introduced and validated independently.
3. Start With One Application at a Time
Even with a well-designed pipeline and selective code strategy, rolling CI/CD out across the entire application portfolio simultaneously is a high-risk move. A better approach is to pick a single application as the pilot.
Criteria for a good pilot application:
- Low business criticality — if something breaks, the impact on customers or revenue is limited.
- Reasonably modern codebase — legacy monoliths with complex build processes make a poor starting point.
- Engaged team — a development team willing to iterate quickly and provide feedback accelerates learning.
Once the pilot application is running through the full pipeline reliably, the team has a reference implementation to replicate. Subsequent onboarding of additional applications becomes faster because the patterns, toolchain configurations, and troubleshooting knowledge already exist. High-priority targets—such as customer-facing microservices or Kubernetes-hosted workloads—can then be migrated with much greater confidence.
4. Limit the Blast Radius to IT First
During the early stages of CI/CD adoption, pipeline failures are inevitable. Misconfigured deployment scripts, flawed rollback procedures, and environment drift are common early problems. To contain the impact of these issues, begin with applications that primarily affect the IT team itself rather than business users or customers.
Internal tooling, developer portals, monitoring dashboards, and internal APIs are good examples. If a deployment fails, the people affected are the engineers who can best diagnose and recover from the situation. This is fundamentally different from a failure in a customer-facing checkout service or a revenue-critical reporting application.
Combining this strategy with the others produces a natural risk hierarchy: start with part of a pipeline, for one class of code, in one IT-internal application. This minimizes the blast radius to its absolute minimum while still generating real operational experience.
Putting It Together: The Go-Slow-Then-Grow Playbook
These four strategies are not mutually exclusive—they work best in combination. A practical starting point might be:
- Choose an internal, non-critical application as the pilot.
- Automate only the build stage initially, using one artifact type (for example, IaC files).
- Expand to additional pipeline stages one at a time, validating each before proceeding.
- Once the full pipeline is stable, onboard additional applications starting with those of moderate criticality.
- Accelerate onboarding as patterns, templates, and operational confidence mature.
The goal of going slow initially is not to stay slow. Once your pipelines are stable, your toolchain is understood, and your team has built operational muscle memory, CI/CD rollouts to higher-stakes applications—including microservices workloads on Kubernetes—can proceed significantly faster. The early investment in careful, incremental adoption pays dividends in speed and reliability at scale.
Key Takeaways
- CI/CD automation touching production systems carries real risk; treat it with the same care as any production change.
- Selecting a narrow code type, a single pipeline stage, and a non-critical pilot application drastically reduces early risk.
- Confining early failures to IT-internal systems limits business and customer impact while the team learns.
- A slow, deliberate start accelerates long-term adoption by producing reusable patterns and confident practitioners.
This article is based on analysis originally published on CMSWire by Tom Petrocelli, contributing analyst at Amalgam Insights, whose research focuses on developer tools, DevOps methodologies, and IT project efficiency.