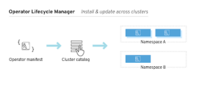
Kubernetes is powerful, but running stateful, production-grade applications on it still demands significant operational expertise. Operators are the Kubernetes-native answer to that problem: software that encodes human operational knowledge and automates routine cluster management tasks for a specific application.
What Is a Kubernetes Operator?
In Kubernetes terms, an operator is a piece of software designed to automate the routine operational tasks required to manage a specific application running on a Kubernetes cluster. The name is a direct analogy to a human computer operator—a role that once involved running shell scripts, transferring files, and handling exceptions, tasks that have largely been automated away over time.
Kubernetes itself was born from a similar need. Google required armies of site reliability engineers to manage its cloud infrastructure, and at a certain scale it became impossible to hire fast enough. The solution was a generic framework—Kubernetes—that could manage clusters of virtual machines running any workload. But Kubernetes is a general-purpose orchestrator. It does not carry domain knowledge about the applications running inside it.
Why Kubernetes Alone Is Not Enough for Stateful Applications
Kubernetes was initially designed with relatively simple, stateless, autonomous workloads in mind—services that can restart anywhere without data loss and handle their own failover. Stateful applications are a different story.
Ravi Lachhman, an evangelist at Harness, describes what he calls the trifecta of a stateful app: clustering, load balancing, and replication. These three capabilities are the hallmarks of highly available systems—think databases like PostgreSQL, message brokers like Kafka, or caching layers like Redis. Managing all three correctly, in the presence of node failures, scaling events, and version upgrades, requires deep application-specific knowledge that a generic orchestrator cannot provide out of the box. That gap is precisely where operators live.
The Five Capability Levels of a Kubernetes Operator
The Kubernetes project defines five levels of operator capability, sometimes called levels of maturity. Each level corresponds roughly to the skill level of the human operator it replaces:
- Level 1 – Basic Install: Provisions or negotiates cluster resources and installs the application. The operator handles the initial deployment so a human does not have to craft complex manifests manually.
- Level 2 – Seamless Upgrades: Manages patch releases and minor version upgrades with minimal disruption, applying upgrades in a controlled, application-aware manner.
- Level 3 – Full Lifecycle: Adds backup and failure recovery. The operator can snapshot state, restore from backup, and recover gracefully from failures without manual intervention.
- Level 4 – Deep Insights: Processes alerts and logs, performs workload analysis, and surfaces actionable intelligence about the application’s health and performance.
- Level 5 – Auto-Pilot: Addresses advanced scaling issues, tunes configuration automatically, and optimises workload scheduling—capabilities Kubernetes does not provide natively for application-specific logic.
Reaching Level 5 is a significant engineering investment, but it essentially replaces a team of specialists for that one application domain.
Finding an Existing Operator
Before writing your own operator, check whether one already exists for your application. OperatorHub.io is the community hub for published, reusable operators. Popular open-source applications—Redis, CouchDB, Kafka, PostgreSQL, and many others—already have operators available there.
The economics of open-source operators are compelling. Writing an operator might cost roughly a person-year of engineering effort, but once published and adopted across many organisations, the accumulated time savings multiply quickly. Deploying a mature operator across thousands of clusters removes the need for equivalent operational expertise at each site.
Some vendors have gone further and certified their operators against the Kubernetes operator capability levels. Portworx, a cloud-native storage provider, is one example of a company that ships a certified operator for its storage platform—removing the need for cluster administrators to manually manage storage provisioning, scaling, and recovery.
When Should You Write Your Own Operator?
Writing a custom operator makes sense when:
- You have an in-house or proprietary application that no existing operator covers.
- Your application exhibits the stateful trifecta—clustering, load balancing, and replication—and the ongoing manual management cost is significant.
- You are operating at a scale where the engineering investment to automate is smaller than the cost of dedicated reliability engineering for that application.
How Operators Are Built
Every Kubernetes operator has two essential components:
- The controller code – The logic that watches cluster state and reconciles it toward the desired state. This is most commonly written in Go (using the Operator SDK or Kubebuilder), but can also be implemented with Ansible or, for simpler use cases, Helm charts.
- A Custom Resource Definition (CRD) – An extension to the Kubernetes API that defines a new resource type. The CRD maps the operator’s capabilities back to familiar
kubectlcommands. Once the CRD is installed, interacting with the operator is as straightforward as creating a YAML manifest and runningkubectl apply.
# Example: applying a custom resource managed by an operator
kubectl apply -f my-application-instance.yamlCode language: PHP (php)
This is the appeal of the operator pattern: it extends Kubernetes rather than working around it. Operators are first-class Kubernetes citizens.
The Hidden Costs of Building Your Own
Writing an operator is not a one-time task. Consider these ongoing commitments before starting:
- Language expertise: The team needs at least one engineer fluent in Go, Ansible, or Helm—ideally more, to avoid a single point of failure.
- Software development lifecycle: Operator code must live in version control, go through code review, and be tested like any other production software.
- Long-term maintenance: As Kubernetes evolves and the target application releases new versions, the operator must be updated accordingly.
- Bus factor: If only one engineer understands the operator, its failure becomes a company-level risk.
For most teams, the right approach is to exhaust the options on OperatorHub before committing to building from scratch. When a mature community operator exists, contributing improvements upstream is almost always cheaper than owning a custom implementation.
Summary
Kubernetes Operators bring application-specific operational intelligence into the cluster itself. They automate the kind of expert, repetitive work that previously required dedicated human operators or expensive reliability engineering teams. For common open-source applications, a ready-made operator likely already exists. For proprietary or highly specialised workloads at scale, writing a custom operator is a legitimate and increasingly common engineering investment—but one that carries real software development overhead and should not be taken lightly.