DevOps adoption has accelerated across organizations of every size, but widespread adoption does not mean widespread success. Teams that rush into implementation without understanding the cultural, procedural, and technical nuances frequently run into the same avoidable problems. The following ten pitfalls are drawn from common patterns observed across DevOps implementations. Use them as a checklist before, during, and after your rollout.
1. Out-of-Order Delivery
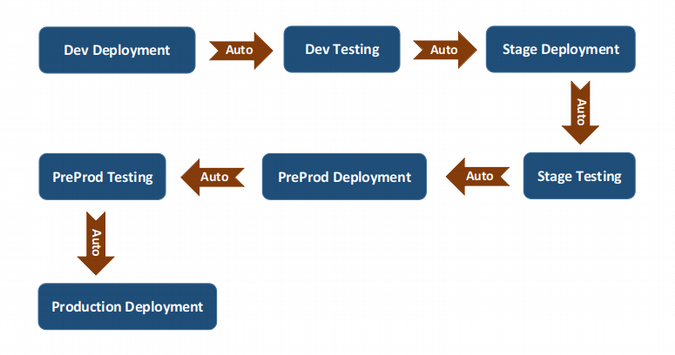
Continuous integration (CI) and continuous delivery (CD) are often implemented together to accelerate feedback cycles—and that combination carries real risk. When teams conflate CI and CD without inserting a proper pre-production stage, incorrectly configured code can reach production before anyone has evaluated its real-world impact. Automated testing alone is not sufficient protection if the pipeline is structured to deploy changes directly to production on a green build.
A staging or pre-production environment that mirrors production is essential. Code should be deployed there first, monitored, and validated by engineers who are familiar with the changes before being promoted further. Structured CD pipelines that gate deployment on explicit approval—rather than fully automatic promotion—help preserve the value of automated testing while adding a human check before customer-facing release.
2. Misunderstanding the DevOps Role
One of the most persistent organizational mistakes is treating the “DevOps engineer” title as a catch-all role expected to solve every problem that touches development and operations. In reality, DevOps is a philosophy of collaboration between those two functions—not a job description for a single superstar.
In practice, DevOps engineers typically specialize. Some focus on platform engineering, pipeline automation, and infrastructure-as-code. Others focus on application reliability, on-call response, and observability. Your organization’s specific needs should dictate where you focus hiring efforts. If automation is the priority, scripting skills and software development experience matter more than deep containerization expertise—at least initially. Hire for learning aptitude and fit your current most critical gap; let people grow into adjacent skills on the job.
3. Treating DevOps as a Rigid Framework
DevOps principles provide a strong foundation, but no single implementation blueprint fits every organization. Teams that follow a prescribed playbook without adapting it to their context often find that the playbook doesn’t survive contact with their actual systems, culture, and constraints.
The CALMS framework—Culture, Automation, Lean, Measurement, and Sharing—offers a useful set of pillars to anchor any DevOps initiative. Within those pillars, teams should feel empowered to define their own KPIs, toolchains, and delivery cadences based on their goals. Inflexibility around process creates bureaucracy that slows teams down rather than enabling them. Build a plan, measure its outcomes, and iterate.
4. Prioritizing Speed Over Quality
A common misreading of DevOps is that it is primarily about shipping faster. Speed matters, but only when it is paired with quality. When KPIs track only deployment frequency or time-to-production, quality signals—test coverage, error rates, performance baselines—get deprioritized and eventually disappear from conversations altogether.
The goal of DevOps is to improve both speed and quality simultaneously. This requires developers and operators to invest in better testing strategies: unit tests, integration tests, contract tests, and meaningful end-to-end scenarios. Done well, increased test coverage and automation make it safe to deploy more frequently, not less. Treating speed and quality as a trade-off is a signal that the testing strategy needs work.
5. Creating a Separate, Siloed DevOps Team
Building a dedicated DevOps team staffed entirely with new hires seems logical—bring in experts, let them lead transformation, and get out of the way. In practice, this approach creates a new silo and generates resentment among existing QA, operations, and development staff who feel excluded from a high-visibility initiative.
A more effective structure blends new team members with current employees who have institutional knowledge, existing relationships, and a stake in the outcome. Those employees understand the existing systems, the political landscape, and where the bodies are buried. That knowledge is invaluable when rolling out changes at scale. Give existing team members the opportunity to participate and grow rather than bypassing them entirely.
6. Overlooking Database Automation
Application code moves through a modern CI/CD pipeline quickly. Database schemas, migrations, and seed data often do not. Teams focus automation efforts on application builds and deployments while leaving database changes as a manual, error-prone step—frequently owned by a single database administrator who becomes a bottleneck.
Without automating database changes, data snapshots across environments drift over time. A staging environment with stale or inconsistent data produces tests that don’t reflect production behavior. Tools for database migration management (schema versioning, migration scripts tracked in version control, automated environment refresh pipelines) should be part of the DevOps strategy from the start, not bolted on later. Data-centric applications in particular require dedicated database automation expertise.
7. Insufficient Incident-Handling Procedures
Faster deployments mean more opportunities for things to go wrong. Organizations that accelerate their delivery cadence without investing in incident management processes will find that production incidents become more frequent, harder to diagnose, and slower to resolve.
Effective incident handling requires documented runbooks, clearly defined escalation paths, on-call rotations, and—critically—blameless post-mortem practices. Blameless post-mortems focus on systemic causes rather than individual fault, producing actionable improvements rather than finger-pointing. Investing in these practices before you need them is far less costly than building them under pressure during an outage.
8. Underestimating the Knowledge Required
DevOps encompasses technical, cultural, and process change simultaneously. Teams often underestimate how much expertise is required to execute all three dimensions well. Engineers who are strong developers may lack infrastructure knowledge. Operations engineers may be unfamiliar with modern testing practices. Leadership may not understand the organizational changes required to break down silos.
Closing these knowledge gaps requires deliberate investment: training programs, hands-on experimentation, access to experienced practitioners, and realistic timelines. In some cases, bringing in external consultants with DevOps implementation experience can accelerate a team’s learning curve—provided those consultants transfer knowledge rather than creating a dependency. Avoid making major toolchain or architectural decisions before your team has a solid grasp of the intended outcomes.
9. Treating Security as an Afterthought
Security is frequently deferred during DevOps implementations because it adds friction to pipelines and requires additional expertise. The result is that applications are shipped quickly, but with vulnerabilities that could have been caught early and cheaply in the development cycle—and are instead discovered late and expensively in production.
DevSecOps addresses this by integrating security practices directly into the CI/CD pipeline: static analysis (SAST), dependency vulnerability scanning (SCA), secrets detection, and infrastructure security scanning all run automatically on every build. Security teams shift from gatekeepers at the end of the cycle to enablers who build guardrails into the pipeline itself. If your organization is not ready for a full DevSecOps implementation, start by adding automated dependency scanning and secrets detection—both are low-effort, high-value first steps.
10. Setting Unrealistic Expectations and Burning Out the Team
DevOps is a long-term cultural transformation, not a project with a fixed end date. Organizations that set aggressive, arbitrary targets—going from quarterly releases to daily deployments in three months, for example—often find that the pressure destroys morale before the transformation takes hold. Engineers burn out, corners get cut, and the initiative loses credibility.
A phased approach with realistic milestones is far more sustainable. Define what success looks like in 90 days, then six months, then a year. Celebrate incremental wins. Build in time for training and experimentation. Recognize that the first CI/CD pipeline will be slow to build and imperfect when it ships—that is normal. Continuous improvement is not a metaphor; it is a literal description of how DevOps matures inside an organization.
Putting It All Together
Every organization’s DevOps journey is different, but the failure modes are remarkably consistent. The ten pitfalls above—rushing pipelines, misdefining roles, rigidity, sacrificing quality for speed, creating silos, ignoring databases, skipping incident processes, underinvesting in knowledge, neglecting security, and burning out the team—have derailed implementations at organizations of every size and maturity level.
The antidote to most of them is the same: invest in culture and process as seriously as you invest in tooling, measure outcomes rather than activity, and treat DevOps as an ongoing practice rather than a destination to reach.
This article is adapted from content originally published on opensource.com.